IBM’s Maximo SQL Server Table (Heap) Fragmentation
Maximo tables by default become fragmented as they are heaps
IBM’s Maximo User Performance
Where I work, we are running two sites with Maximo 7.6 and the users do not have an issue with the performance, most of the ‘power users’ love the system so when I criticise it I feel a bit out of step.
Maximo is an old system and the implementation is old and this is a serious bottleneck on the system. The front end interface is easy to change but in internals is much harder.
All Maximo tables are heaps – All tables within Maximo are heaps, if data is modified and deleted they can become fragmented and have holes. (Heaps are tables without a clustered index).
Basics
Tables – A table (not a heap) has a clustered index which should be the primary key. The table is the index, the data is stored in the order defined by the clustered index. When rows are added or deleted, the server manages changes; when the data in a row increases, for example, inserting into a null column, if the block holding the data isn’t large enough the server creates a page split and the data is shared across two blocks. Inserting, deleting and updating does not create fragmentation in the table.
Heaps – Heaps are that, the data is stored as inserted into the table in no particular order and each row is assigned a system row identifier rid. When data is inserted it’s added to the end of the table when data is deleted, the blocks where the data used still remain part of the table until the table is rebuilt but these unused blocks as still accessed during a table scan. When a row is altered and there isn’t enough space in the blocks to hold the data is moved to a new location and a forward pointer is created in the table to point to this new area. Only be rebuilding the table will clean up the forward pointers but this also forces a rebuild of any table indexes.
The problem with rebuilding heaps – The issue with rebuilding a heap is that with ‘Standard SQL Server’ it takes the heap offline, if you have the ‘Enterprise’ version the heap can be kept online during the rebuild. With our production database, the biggest heap on our takes around two hours to rebuild.
Why use heaps? – Heaps are faster for inserts and for ‘Key/RID lookups’. The RID enables faster row location than an index id but only if the heap is not fragmented.
Key lookup has to find the identify the page(s) which hold the index, from that identify the page to collect the row id then open the page with that id.
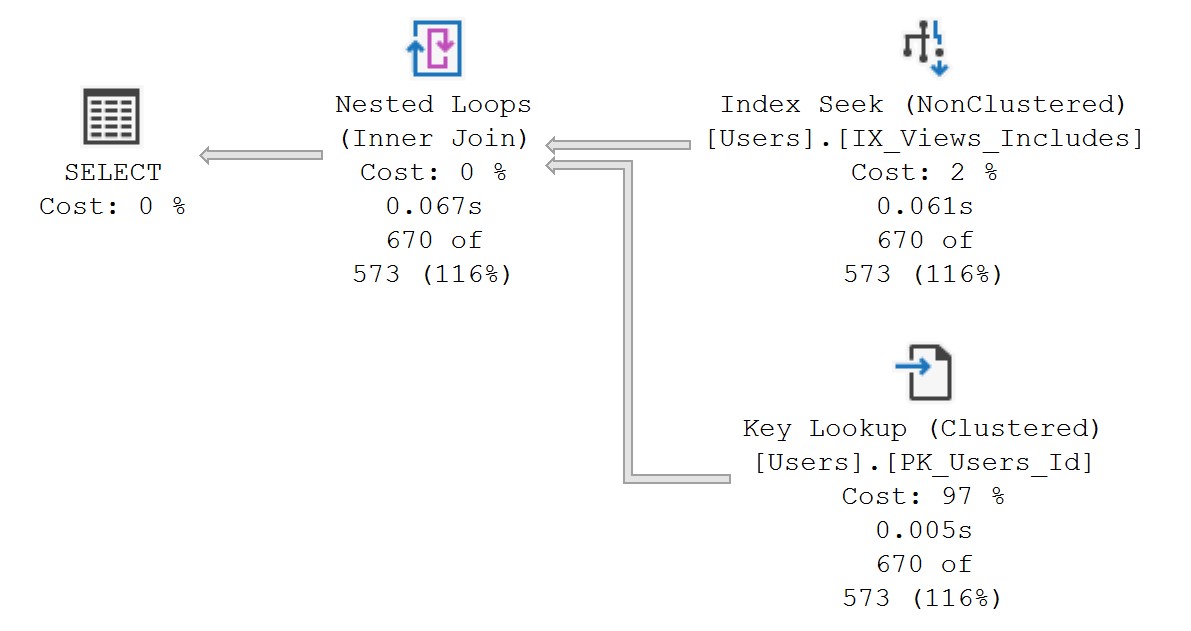
Key lookup
RID lookup as the RID holds the ‘page number’, ‘slot number’ and the ‘row’ it can skip the first to step a key lookups neeto take so reading data with lookups are marginally faster.
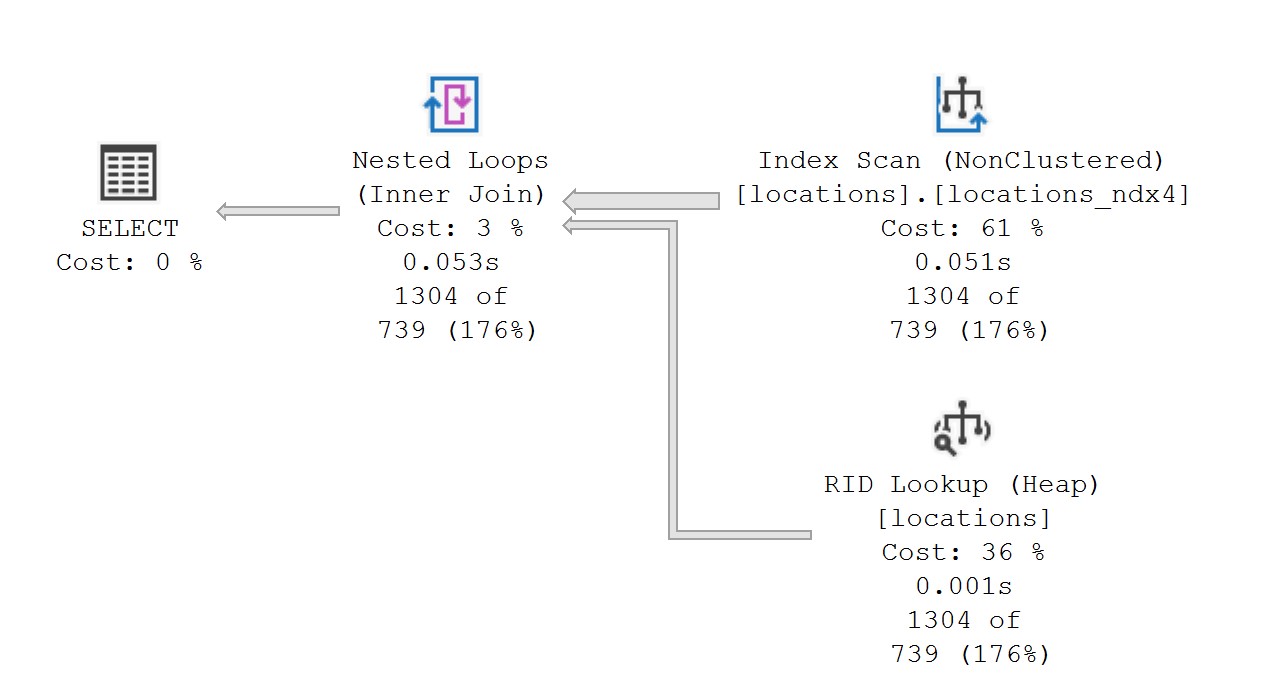
RID lookup
Maximo uses heaps as tables – this means the tables can have unused block and forward lookups which slows the system down. This might have been a performance enhancement ten years ago but heaps are not an advantage now. This isn’t an exclusive issue with Maximo and SQL Server, before we migrated the data from our Oracle instance we had issues with ‘block chaining’ which is similar to SQL Server ‘forward lookups’ and the performance of the system would become a serious issue.
Checking the health of heaps – I used two SQL scripts which give slightly different information about heaps. The first query is slower than the first.
/* forward fetch count on Dev took 17 mins to run*/
SELECT OBJECT_NAME(OBJECT_ID) AS table_name,
       forwarded_record_count, /* Number of records in a heap that have forward pointers to another data location. */
       avg_fragmentation_in_percent, /* Extent fragmentation for heaps in the IN_ROW_DATA allocation unit. */
       page_count /* Total number of data pages. */
FROM sys.dm_db_index_physical_stats(DB_ID(), DEFAULT, DEFAULT, DEFAULT, 'DETAILED')
WHERE forwarded_record_count <> 0
ORDER BY 3 DESC;
The output from the query is below and it gives a good summary of the status your heaps:
| table_name | forwarded_record_count | avg_fragmentation_in_percent | page_count |
| workorder | 118 | 9.805747249 | 4570252 |
| wostatus | 638 | 13.17411125 | 887828 |
| multiassetlocci | 36 | 11.05582396 | 829461 |
| workview | 11112 | 18.15360944 | 623885 |
| locationspec | 119 | 20.1733689 | 467883 |
| assetspec | 229 | 22.56323893 | 465526 |
| locations | 17047 | 7.540335858 | 24292 |
| route_stop | 1 | 0.2066115702 | 11599 |
| lochierarchy | 3 | 6.755373593 | 7792 |
| locoper | 12 | 12.73291925 | 7719 |
| assignment | 30 | 4.47761194 | 6419 |
| jobplan | 1 | 3.064516129 | 4949 |
| jobtask | 1 | 0.1821493625 | 4380 |
| person | 5 | 81.81818182 | 81 |
| maxsysindexes | 97 | 28.57142857 | 50 |
| reportsched | 5 | 66.66666667 | 17 |
| maxuser | 3 | 33.33333333 | 15 |
The query below runs relatively fast and like all lazy coders I print out the query to rebuild the heap:
/* forward fetch usage and rebuild command */
SELECT os.forwarded_fetch_count /* Count of rows that were fetched through a forwarding record. */
       ,OBJECT_NAME(os.OBJECT_ID, os.database_id) AS table_name
       ,command = N'ALTER TABLE ' + QUOTENAME(DB_NAME(os.database_id)) + N'.'
                 + QUOTENAME(OBJECT_SCHEMA_NAME(os.OBJECT_ID, os.database_id)) + N'.'
                 + QUOTENAME(OBJECT_NAME(os.OBJECT_ID, os.database_id)) + N' REBUILD WITH (ONLINE=OFF, MAXDOP=0);'
       ,heap_size_mb = CAST(ps.reserved_page_count * 8.0 / 1024. AS BIGINT) /* reserved_page_count - Total number of pages reserved. in_row_reserved_page_count + lob_reserved_page_count + row_overflow_reserved_page_count. */
       ,nonclustered_indexes =
       (
           SELECT COUNT(DISTINCT i.index_id)
           FROM sys.indexes i
           WHERE os.OBJECT_ID = i.OBJECT_ID
                 AND i.index_id <> 0
                 AND i.is_disabled = 0
                 AND i.is_hypothetical = 0
       )
       --SELECT COUNT(*)
FROM sys.dm_db_index_operational_stats(DB_ID(), NULL, NULL, NULL) os
    INNER JOIN sys.dm_db_partition_stats ps
        ON ps.OBJECT_ID = os.OBJECT_ID
           AND ps.index_id = os.index_id
           AND ps.partition_number = os.partition_number
WHERE os.index_id = 0
      AND os.forwarded_fetch_count > 0
ORDER BY os.forwarded_fetch_count DESC;
The output is from the script above is below:
| forwarded_fetch_count | table_name | command | heap_size_mb | nonclustered_indexes |
| 1280651 | locations | ALTER TABLE [max76UAT].[dbo].[locations] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 189 | 11 |
| 3506 | workview | ALTER TABLE [max76UAT].[dbo].[workview] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 4874 | 2 |
| 2978 | workorder | ALTER TABLE [max76UAT].[dbo].[workorder] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 35710 | 39 |
| 1455 | maxsysindexes | ALTER TABLE [max76UAT].[dbo].[maxsysindexes] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 0 | 3 |
| 208 | person | ALTER TABLE [max76UAT].[dbo].[person] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 0 | 10 |
| 201 | maxuser | ALTER TABLE [max76UAT].[dbo].[maxuser] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 0 | 5 |
| 172 | locoper | ALTER TABLE [max76UAT].[dbo].[locoper] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 60 | 3 |
| 97 | reportsched | ALTER TABLE [max76UAT].[dbo].[reportsched] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 0 | 3 |
| 64 | jobplan | ALTER TABLE [max76UAT].[dbo].[jobplan] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 38 | 9 |
| 55 | assignment | ALTER TABLE [max76UAT].[dbo].[assignment] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 50 | 7 |
| 20 | assetspec | ALTER TABLE [max76UAT].[dbo].[assetspec] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 3637 | 4 |
| 7 | locationspec | ALTER TABLE [max76UAT].[dbo].[locationspec] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 3655 | 5 |
| 5 | route_stop | ALTER TABLE [max76UAT].[dbo].[route_stop] REBUILD WITH (ONLINE=OFF, MAXDOP=0); | 90 | 7 |
The smaller heaps can be quickly rebuilt in seconds but the larger tables are too big to be rebuilt without causing an issue.
From the results from the query rebuilding the ‘locations’ table which is relatively small and has the highest forward record count and forward record fetch count will help performance.
Heap maintenance
I use Ola Hallengren’s maintenance scripts but if you want the index maintenance to rebuild the heaps you need to alter the script. Brent Ozar did a post about altering the script to rebuild heaps ‘How To Fix Forwarded Records‘. The only problem as been if you run this you could knock out the system for hours fixing the issues with your heaps so think carefully about the issue. I enabled the heap rebuild but then I disabled it as it caused too many issues. I normally plan heap rebuilds to ensure we do not have any issues and the users are happy less grumpy.
Summary
Heaps were only created for ‘Extract Transform and Load’ (ELT) process and not for use in production systems. I have raised this issue with IBM but nothing is going to change in the short term. If you want good performance you need to ensure the heaps are not fragmented, do not have many forward lookups which are being used. The only blunt tool to fix these issues is a table rebuild which also rebuilds all the heaps indexes and unless the server is the enterprise edition takes the heap off-line.